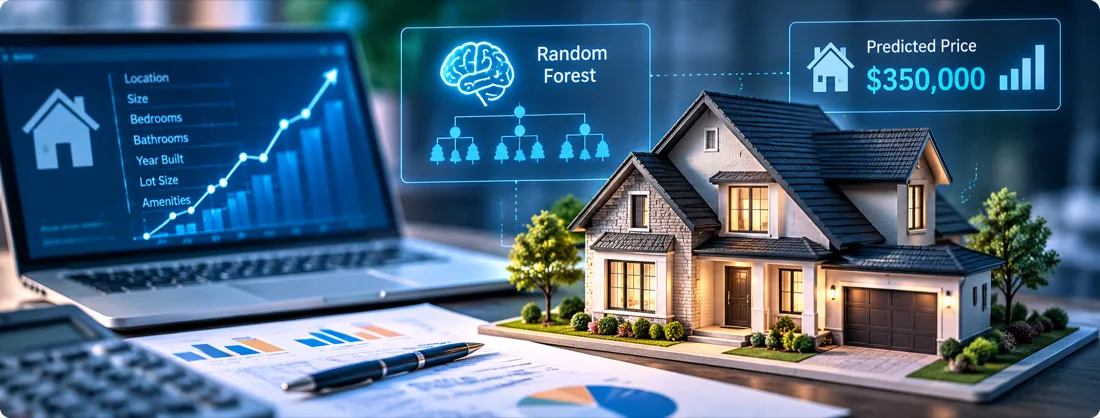
Predicting house prices is a standard regression problem and a useful way to learn a complete machine learning workflow: preparing data, choosing features, training a model and evaluating whether the result is actually any good. Random Forest is a sensible starting algorithm for this kind of structured, tabular data.
Why Random Forest for this problem
A Random Forest builds many decision trees on random subsets of the data and features, then averages their predictions. That averaging is what makes it useful here:
- It handles non-linear relationships without needing them specified in advance
- It is relatively tolerant of outliers and unscaled features
- It reduces the overfitting a single deep decision tree is prone to
- It reports feature importance, which helps explain the model
The trade-off is interpretability. A single tree can be read directly; a forest of hundreds cannot.
Preparing the data
Housing datasets usually mix numeric columns (area, number of rooms, age) with categorical ones (location, property type). Models need numbers, so categories must be encoded:
import pandas as pd

df = pd.read_csv("housing.csv")

# separate target from features
y = df["price"]
X = df.drop(columns=["price"])

# one-hot encode categorical columns
X = pd.get_dummies(X, drop_first=True)
drop_first=True avoids creating perfectly redundant columns. Tree models are less sensitive to this than linear models, but it keeps the feature count down.
Splitting into train and test
from sklearn.model_selection import train_test_split

X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, random_state=42
)
The test set must be held back and never used during training or tuning. Evaluating on data the model has already seen tells you how well it memorised, not how well it generalises.
Training the model
from sklearn.ensemble import RandomForestRegressor

model = RandomForestRegressor(
    n_estimators=100,
    random_state=42,
    n_jobs=-1
)
model.fit(X_train, y_train)
n_estimators is the number of trees. More trees generally help up to a point, after which the gain is marginal and training simply takes longer.
Evaluating honestly
Accuracy is not a meaningful term for regression. The common metrics are:
from sklearn.metrics import mean_absolute_error, mean_squared_error, r2_score
import numpy as np

preds = model.predict(X_test)

mae  = mean_absolute_error(y_test, preds)
rmse = np.sqrt(mean_squared_error(y_test, preds))
r2 = r2_score(y_test, preds)- MAE — average error in the same unit as price. The easiest to explain to a non-technical audience.
- RMSE — penalises large errors more heavily, so it is sensitive to a few bad predictions.
- R² — proportion of variance explained. Useful for comparison, but easy to over-interpret in isolation.
Report MAE or RMSE in currency terms rather than quoting R² alone. "Typically within X of the actual price" is far more meaningful to a reader than a score between 0 and 1.
Understanding what drove the predictions
importances = pd.Series(
    model.feature_importances_, index=X.columns
).sort_values(ascending=False)

print(importances.head(10))
Feature importance is a useful sanity check. If something trivial dominates, there may be leakage — a feature that indirectly encodes the price and would not be available when predicting a genuinely unseen property.
Common pitfalls
- Data leakage — including a column derived from the target
- Evaluating on training data — produces impressively wrong results
- Ignoring the distribution — a long right tail of expensive properties can distort both training and metrics
- Assuming it transfers — a model trained on one city's market will not necessarily work in another
Where to go next
Once a baseline forest is working, the usual next steps are cross-validation for a more stable estimate of performance, hyperparameter tuning with grid or random search, and comparing against gradient boosting methods, which often perform better on tabular data at the cost of more careful tuning.