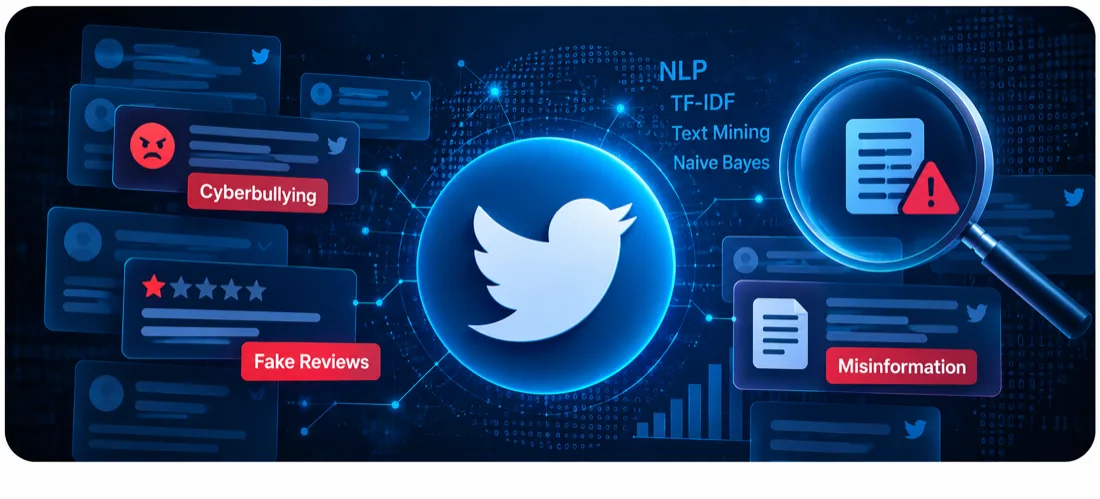
Social platforms carry a large volume of text that no moderation team can review manually. Natural Language Processing offers a way to flag likely fraudulent or harmful content automatically — fake reviews, scam messages, coordinated misinformation — so that human reviewers can concentrate on the cases that matter. This post outlines how such a pipeline is typically built.
Framing the problem
Most of this work reduces to text classification: given a piece of content, assign it to a category such as genuine or suspicious. The difficulty is rarely the algorithm. It is that fraudulent text is written specifically to look legitimate, and that the people producing it adapt once they understand what is being detected.
Preparing the text
Raw social text is noisy. A typical preprocessing sequence:
- Lowercase the text so casing does not split otherwise identical tokens
- Strip URLs, user mentions and HTML entities
- Remove or normalise punctuation and emoji, depending on whether they carry signal
- Tokenise into individual words
- Remove stopwords that add little discriminating value
- Apply stemming or lemmatisation to collapse inflected forms
import re

def clean(text):
    text = text.lower()
    text = re.sub(r"http\S+", " ", text)
    text = re.sub(r"@\w+", " ", text)
    text = re.sub(r"[^a-z\s]", " ", text)
    return re.sub(r"\s+", " ", text).strip()
Each of these steps discards information, so they are choices rather than defaults. Excessive punctuation or capitalisation can itself be a signal, and stripping it removes a feature the model might have used.
Turning text into features with TF-IDF
Models need numbers. TF-IDF — term frequency–inverse document frequency — weights each word by how often it appears in a document against how common it is across the whole corpus. Words that appear everywhere get low weight; words distinctive to a document get high weight.
from sklearn.feature_extraction.text import TfidfVectorizer

vectorizer = TfidfVectorizer(
    max_features=5000,
    ngram_range=(1, 2),
    min_df=2
)
X = vectorizer.fit_transform(texts)
Including bigrams via ngram_range=(1, 2) captures short phrases, which often matter more than individual words for this kind of detection.
Naive Bayes as a baseline
Multinomial Naive Bayes is a standard first model for text classification. It is fast to train, works well with sparse high-dimensional features, and gives a baseline that more complex models must beat to justify themselves.
from sklearn.naive_bayes import MultinomialNB
from sklearn.model_selection import train_test_split

X_train, X_test, y_train, y_test = train_test_split(
    X, labels, test_size=0.2, random_state=42, stratify=labels
)

model = MultinomialNB()
model.fit(X_train, y_train)
The stratify argument matters here. Fraud datasets are usually imbalanced, and without stratification a random split can leave very few positive examples in the test set.
Evaluating on imbalanced data
Accuracy is misleading when one class dominates. If 95% of content is genuine, a model that labels everything genuine is 95% accurate and completely useless. Use precision, recall and F1 instead:
from sklearn.metrics import classification_report, confusion_matrix

preds = model.predict(X_test)
print(classification_report(y_test, preds))
print(confusion_matrix(y_test, preds))- Precision — of the items flagged, how many were genuinely fraudulent. Low precision means wasted reviewer time and unfairly flagged users.
- Recall — of the genuinely fraudulent items, how many were caught. Low recall means fraud passing through.
- F1 — the harmonic mean, useful as a single comparison figure.
The balance between precision and recall is a product decision, not a technical one. Flagging content for human review tolerates lower precision; automatic removal demands high precision.
Practical difficulties
- Labelled data is scarce. Supervised learning needs examples confirmed as fraudulent, and these are expensive to obtain and often ambiguous.
- Adversaries adapt. Detection changes the behaviour it is detecting, so models degrade over time and need retraining.
- Context is missing. Text alone omits account age, posting frequency and network relationships, which are often stronger signals than wording.
- Mistakes have real cost. A false positive means a legitimate user is penalised. Any deployed system needs an appeal route.
Beyond the baseline
Linear SVMs and logistic regression on TF-IDF features frequently outperform Naive Bayes while remaining fast. Transformer models such as BERT capture word order and context that bag-of-words representations discard, at substantially higher computational cost. The appropriate choice depends on data volume, latency requirements and how much explainability the application needs.