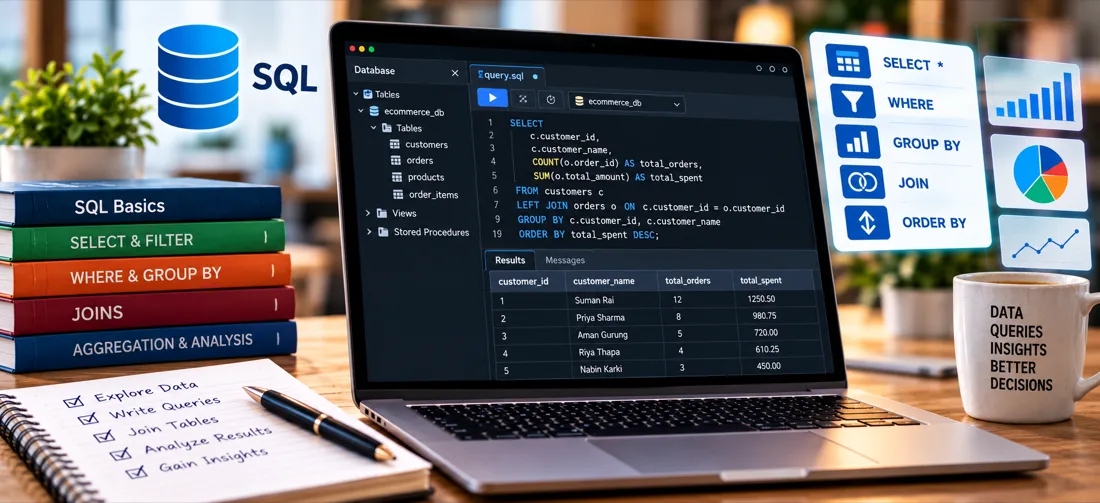
SQL remains the most direct way to answer questions about data held in a relational database. For analysis work, a relatively small part of the language covers most of what you need. This post walks through those core operations in roughly the order you would use them.
SELECT and WHERE
Every query starts by choosing columns and rows:
SELECT first_name, last_name, city
FROM customers
WHERE city = 'Kathmandu';
Avoid SELECT * in anything you intend to keep. Naming columns makes the query self-documenting and avoids breaking when the table changes.
Conditions can be combined, and parentheses make the intent explicit:
SELECT *
FROM orders
WHERE (status = 'shipped' OR status = 'delivered')
  AND order_date >= '2024-01-01';
Useful WHERE operators
IN— match any value in a list:WHERE city IN ('Kathmandu', 'Pokhara')BETWEEN— inclusive range:WHERE price BETWEEN 100 AND 500LIKE— pattern matching:WHERE email LIKE '%@gmail.com'IS NULL— test for missing values. Note that= NULLnever matches anything.
Sorting and limiting
SELECT product_name, price
FROM products
ORDER BY price DESC
LIMIT 10;
Applying LIMIT while exploring an unfamiliar table is a good habit — it keeps an accidental query against millions of rows from becoming a problem.
Aggregating with GROUP BY
Most analytical questions are aggregations:
SELECT city,
       COUNT(*)      AS customer_count,
       AVG(total)    AS average_order,
       MAX(total)    AS largest_order
FROM orders
GROUP BY city
ORDER BY customer_count DESC;
Every column in the SELECT must either appear in GROUP BY or be wrapped in an aggregate function. This is the rule that causes most early errors.
HAVING versus WHERE
These are frequently confused. WHERE filters individual rows before grouping; HAVING filters groups after:
SELECT city, COUNT(*) AS order_count
FROM orders
WHERE status = 'completed'     -- filters rows first
GROUP BY city
HAVING COUNT(*) > 50;          -- then filters groups
Joining tables
Data worth analysing is usually spread across tables:
SELECT c.first_name,
       c.last_name,
       o.order_date,
       o.total
FROM customers c
INNER JOIN orders o ON o.customer_id = c.id
WHERE o.total > 1000;
The join types you will actually use:
- INNER JOIN — only rows with a match on both sides
- LEFT JOIN — all rows from the left table, with NULLs where there is no match
- RIGHT JOIN — the mirror image, and rarely needed in practice
A LEFT JOIN is the standard way to find missing relationships:
SELECT c.first_name, c.last_name
FROM customers c
LEFT JOIN orders o ON o.customer_id = c.id
WHERE o.id IS NULL;   -- customers who have never ordered
Subqueries
SELECT product_name, price
FROM products
WHERE price > (SELECT AVG(price) FROM products);
Subqueries are readable for a single level. Beyond that, a common table expression is usually clearer:
WITH city_totals AS (
    SELECT city, SUM(total) AS revenue
    FROM orders
    GROUP BY city
)
SELECT *
FROM city_totals
WHERE revenue > 100000;
The order SQL actually executes
Queries are written SELECT first but evaluated roughly in this order:
FROMandJOIN— assemble the rowsWHERE— filter rowsGROUP BY— form groupsHAVING— filter groupsSELECT— choose columnsORDER BYthenLIMIT
Knowing this explains several otherwise puzzling errors — notably why a column alias defined in SELECT cannot be referenced in WHERE, but can be in ORDER BY.
Habits worth forming
- Build complex queries incrementally, checking the output at each stage
- Use table aliases consistently to keep joins readable
- Comment the intent of anything non-obvious
- Run a
SELECTbefore the equivalentUPDATEorDELETEto confirm which rows are affected